The challenge
A Fortune 500 financial services client needed to compare the performance of agentic workflows to traditional human-only teams. The focus was quality, suitability, and efficiency under real-world, post-deployment conditions.
Our approach
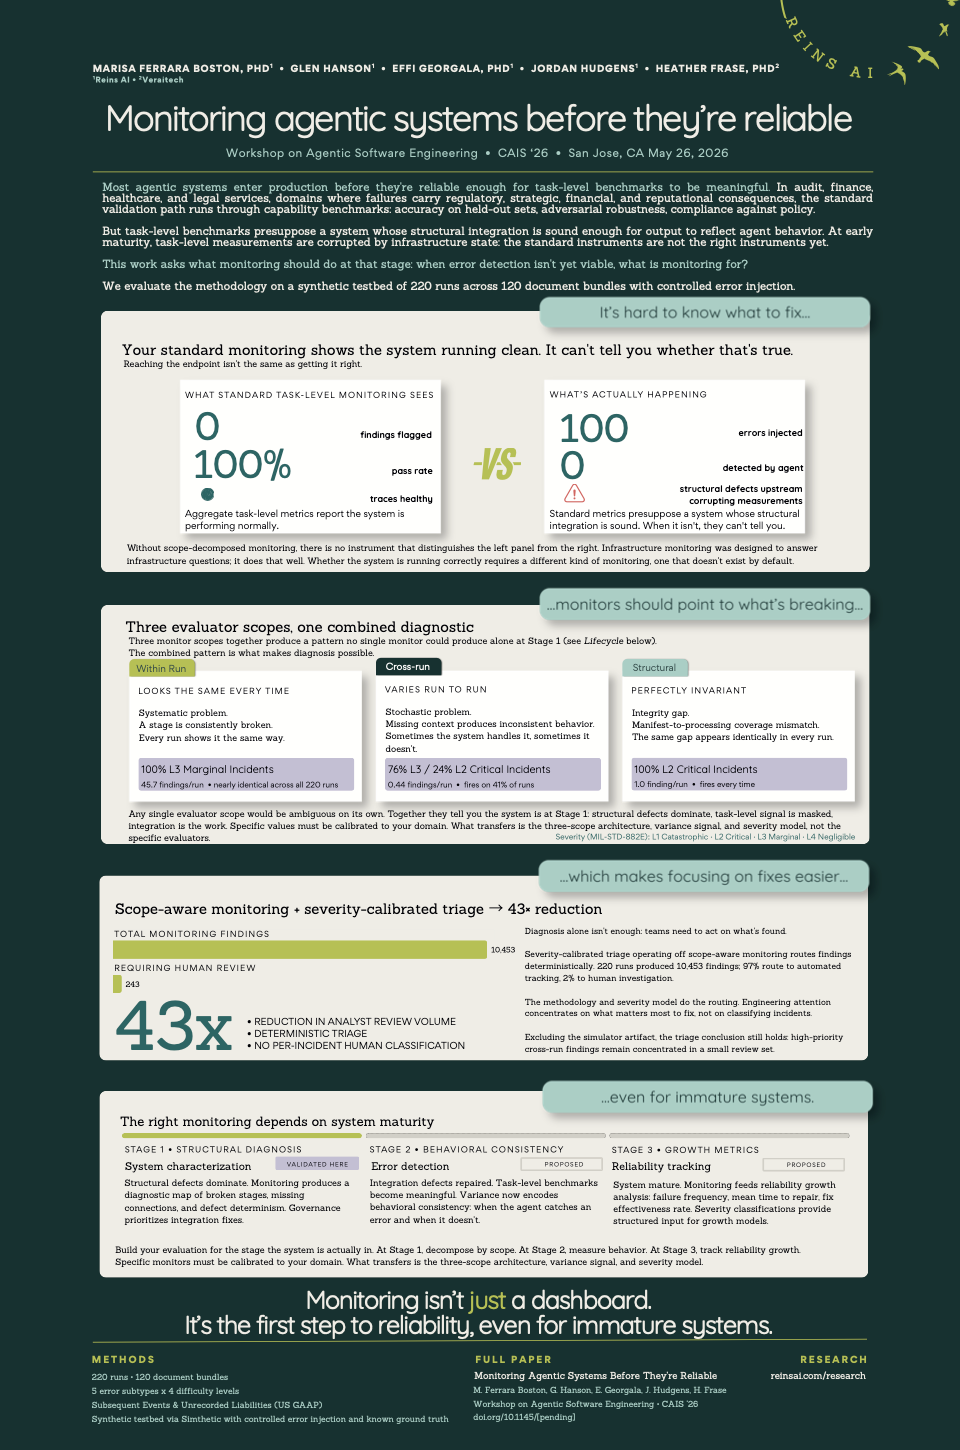
We created a scalable evaluation methodology for agentic systems that combined agent logs, human outputs, error categorization, and impact-weighted scoring. We aligned success metrics with business thresholds and regulatory benchmarks. The methodology enabled not just measurement, but identification of where agents underperformed and why.
Outcome
The client received a dashboard of performance over time, with drill-downs into failure cases and adaptation guidance. This became part of their broader AI monitoring practice.
What it shows
Evaluating AI workflows isn’t just about measuring accuracy, it’s about surfacing gaps in suitability and creating a path to useful adaptation. This project highlights Reins AI’s strength in building evaluation methods tied to real operational goals.